- Home
- Recruitment data scraping
Job postings and salary data, delivered as clean data.
We collect postings and salaries, skills and company details from public job boards and company career pages.
Built around your roles and markets, delivered on your schedule.
Get a free sample from your own sources within 24 hours and see the data before you commit.
| job_title | company | location | salary | days_open | status |
|---|---|---|---|---|---|
| Northwind Group | Austin | $72-95K | 34 | ▲ 7.1% | |
| Harbor Logistics | Chicago | $85-110K | 6 | new | |
| Summit Health | Denver | $68-84K | 52 | unchanged | |
| Brightline Labs | Remote | $95-120K | 41 | ▲ 4.9% | |
| Pine Ridge Grill | Portland | $38-46K | 41 | closed |
Trusted by 500+ companies, startups and individuals.

Every field you need from a job posting.
These are the usual building blocks. We add or drop fields to fit your project, and the free sample shows exactly what comes back.
Job
What the role is.
- job_title
- job_type
- seniority
- experience_level
- department
- industry
- skills
- remote_option
- description
Salary and benefits
What the role pays, and what comes with it.
- salary_min
- salary_max
- currency
- pay_period
- salary_type
- bonus
- benefits
Company
Who is hiring. Public company details only.
- company_name
- company_website
- company_size
- company_industry
- headquarters
- company_rating
- career_page_url
Location
Where the job is.
- city
- region
- country
- postcode
- remote_regions
- work_mode
- latitude
- longitude
Posting history
How each posting changes over time.
- posted_date
- first_seen
- last_seen
- days_open
- status
- closed_on
- reposted_count
- salary_changes
- duplicate_of
Source and application
Where the posting was found, and where to apply.
- source_urls
- sources_count
- apply_url
- apply_method
- posting_id
- last_checked
On requestEmployer ratings, salary reports, company career-page changes, and hiring trends by company or role, where they are published.
How teams put recruitment data to work.
Job boards and aggregators
Fill your job board with postings from many sources, matched to one record per job, and remove listings that have closed.
Recruitment agencies
Find companies that are hiring for the roles you place, see how long their postings stay open, and get in touch while the role is still open.
HR and compensation teams
Benchmark salary ranges by role, level and city, and see how competitors change their pay when roles stay open.
Analysts and investors
Track hiring by company, sector or region as an early signal of growth, cuts or a change of strategy.
Why job data is harder than it looks.
A scraped job list can look complete and still be full of duplicates and dead postings. These are the five problems we plan for, and how we handle each.
Search results are capped.
Job boards show only the first few pages of results for each search, so a single query sees only a slice of the market.
We split the search by role, location, date and salary band so coverage is complete, and each run reports how many postings it found.
The same job is posted everywhere.
Employers and agencies post one role to several boards and to their own career page, each with a different title and description.
We match postings by company, title, location and description, then merge them into one record that keeps every source.
Postings close without notice.
Filled and withdrawn roles disappear, and some boards keep showing old ones.
Scheduled re-checks mark a posting as closed when it disappears from its source, and every record carries first-seen, last-seen and days-open dates.
Salaries are missing or inconsistent.
Pay is shown per hour, month or year, in different currencies, as a range, or not at all.
We normalize pay to one period and currency, keep the original range, and note where a board shows an estimate instead of a stated salary.
Sites block and change.
Job boards use bot protection and redesign their pages, and scrapers quietly return half the rows.
Every pipeline is monitored with row-count and field checks. When a site changes or blocks us, we fix it. Maintenance is part of the service.
From your list of job sources to a live data feed.
Tell us what you need
Share the job boards or career pages, the roles and locations, and the fields. A short call or a message is enough.
See a free sample
Within 24 hours of the call, depending on the sources, you get a sample from your own sources. You see the fields, the quality and the refresh rate before you commit.
Pick the schedule
Hourly, daily, weekly or monthly. We scope the price once you have seen the sample.
Receive and rely on it
Data arrives as CSV, JSON, Excel, Google Sheets, Airtable, in your database, through an API or in cloud storage. We monitor it and fix what breaks.
Straight answers.
What teams ask before they start.
What recruitment data can you collect?
Job postings with title, company, location, salary range, job type, skills and description, plus posting and closing dates and application links. On request we also collect employer ratings, salary reports and company career-page changes. Tell us the fields you need and the free sample shows what is possible.
Can you track postings that change or close?
Yes. We re-check your sources on a schedule from hourly to monthly and store every change. You get salary changes, days open and closing dates, not just a snapshot. A posting that disappears is marked closed. We cannot tell whether the role was filled or withdrawn.
How do you handle the same job on several boards?
We match postings by company, title, location and description and merge them into one record that keeps every source. You can receive merged records, raw records or both.
Which job boards and countries can you cover?
Large national job boards, niche boards, company career pages and applicant tracking system sites, in any country and language. If a source is not practical, for example because of heavy blocking, we tell you upfront, before you commit to anything.
Is scraping job websites legal?
We collect publicly available data only. Rules differ by country and by site, a site's terms may restrict automated access, and postings can include personal details such as a recruiter's name or email address, which need extra care under laws like GDPR. We flag risky sources and fields before we build. We are not lawyers, so for sensitive uses we recommend checking with your own counsel.
How do I receive the data?
CSV, JSON, Excel, Google Sheets, Airtable, your own database, an API or cloud storage, on a schedule you choose.
How much does it cost, and how fast can we start?
Pricing depends on sources, volume and frequency. We scope it after a free discovery call and sample. Most samples are ready within 24 hours of the call, depending on the sources.
Your free job data sample, built on your actual sources.
Tell us the job boards, roles, locations and fields you need. We reply with a plan and a sample.
Prefer to talk first? Book a call with the founder
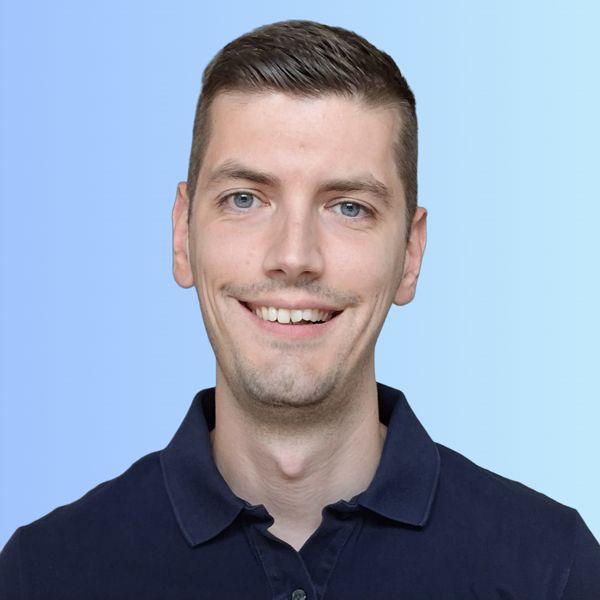
Lazar Telebak
You work directly with the person who builds your data feed. In 10+ years he has worked with 500+ startups, agencies and companies, from one-time extractions to long-running systems processing tens of millions of records.
Founder profile on LinkedIn ↗